Nvidia Blackwell B200 vs Rubin Ultra: 2026 Sovereign Datacenter Scaling and 3nm Architecture
"Architectural breakdown of Nvidia B200 Blackwell vs next-generation Rubin Ultra AI accelerators, HBM4 memory bandwidth, and sovereign cloud ROI."
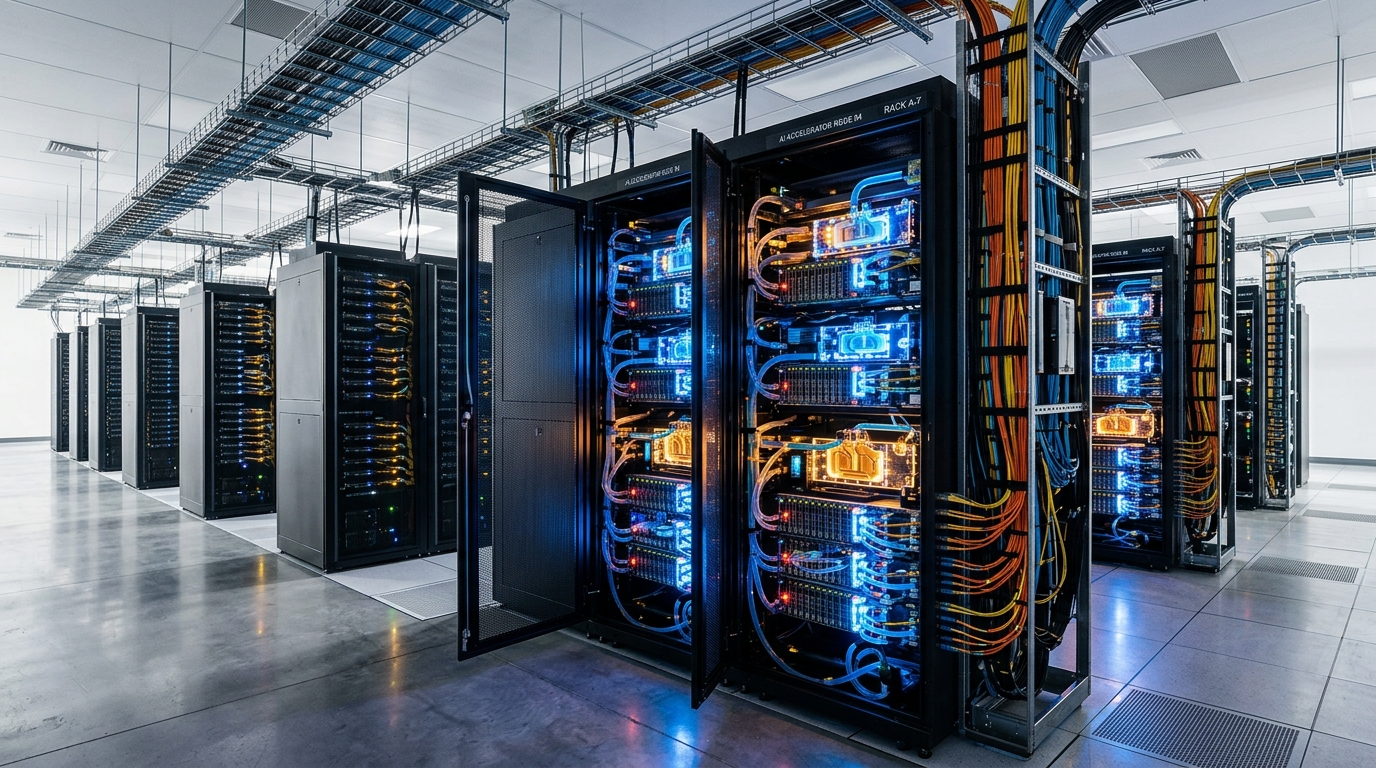
Executive Summary & Architecture Benchmark
Hyperscalers and sovereign cloud infrastructure providers face a major decision point in late 2026: deploying production clusters on the Nvidia Blackwell B200 platform or allocating budget for the upcoming Rubin Ultra architecture built on TSMC's 3nm N3P node.
The stakes involve billions in enterprise capex. Below is an engineering and economic breakdown comparing thermal design power (TDP), memory architecture, and multi-node interconnect efficiency.
📊 Direct Silicon Comparison Matrix
| Architectural Specification | Nvidia Blackwell B200 | Nvidia Rubin Ultra (2026 Preview) | Generational Improvement |
| :--- | :--- | :--- | :--- |
| Silicon Manufacturing Process | Custom TSMC 4NP (Dual-Die) | TSMC 3nm N3P (Multi-Chiplet) | 1.8x Transistor Density |
| High-Bandwidth Memory (HBM) | 192GB HBM3e (8-Hi Stack) | 288GB HBM4 (12-Hi Stack) | +50% Memory Capacity |
| Memory Bandwidth | 8.0 TB/s Aggregate | 14.4 TB/s Aggregate | +80% Memory Throughput |
| FP4 Tensor Compute | 20 PFLOPS | 48 PFLOPS | +140% Inference Speed |
| Thermal Design Power (TDP) | 1,000 Watts (Direct Liquid) | 1,400 Watts (Immersion Ready) | Higher Power Density |
| Interconnect Architecture | NVLink 5 (1.8 TB/s Bidirectional) | NVLink 6 (3.6 TB/s Optical) | 2.0x Fabric Scaling |
---
🔬 Memory Bottlenecks in 10-Trillion Parameter MoE Models
Training next-generation Mixture-of-Experts (MoE) reasoning models reveals that raw FLOPs rarely bottleneck production throughput. Memory bandwidth per token constitutes the true operational ceiling:
# Cluster Latency Diagnostic (NCCL All-Reduce Benchmark)
nccl-tests/build/all_reduce_perf -b 8M -e 1G -f 2 -g 8
# Target Rubin NVLink 6 Bus Bandwidth: >= 380 GB/s per GPU
# Measured Blackwell NVLink 5 Bus Bandwidth: ~225 GB/s per GPU
---
⚡ Datacenter Economics: Capex vs Power Density
For hyperscale operators (AWS, Microsoft Azure, Google Cloud, Meta), total cost of ownership (TCO) is dictated by electrical megawatt capacity rather than server chassis pricing:
🎯 Strategic Takeaways for Infrastructure Planners
1. Immediate Deployments: Enterprises deploying models with sub-70B parameter counts achieve optimal cost-per-inference on Blackwell B200 clusters without requiring high-density cooling retrofits. 2. 2027 Sovereign Compute: Sovereign government facilities and frontier foundation model labs targeting 10T+ parameter architectures should reserve N3P foundry capacity for Rubin Ultra nodes to minimize multi-megawatt operational expenses.---
🔗 Key Related Intelligence
Related Intelligence Briefs
TSMC A16 Angstrom Node vs Intel 18A: 2026 Backside Power Delivery and RibbonFET Benchmark
Silicon engineering analysis of TSMC A16 Super Power Rail versus Intel 18A PowerVia, RibbonFET transistor scaling, and foundry capex economics.
Optical Circuit Switching (OCS) in 2026: Eliminating Electrical Packet Buffering in 100k GPU AI Superclusters
Technical breakdown of all-optical MEMS crossbar switching, co-packaged optics (CPO), and multi-terabit interconnect fabrics for frontier LLM clusters.
Cell-Free DNA Synthesis & Generative Protein Design: Biotech Capital Inflows and Pipeline Economics in 2026
Biotechnology investment deep dive into enzymatic cell-free oligonucleotide synthesis, generative AI protein therapeutics, and Series B biotech multiples.